Aestus follows every change in your databases and delivers it to your targets, in order and exactly where it belongs: other databases, the lakehouse, graphs, search indexes, vector stores, application APIs and your enterprise event brokers. It runs continuously, loses nothing, and your data never leaves your network.
A change passes through a few small agents, connected by a durable message broker. Each agent does one job for one kind of system; together they form a flow.
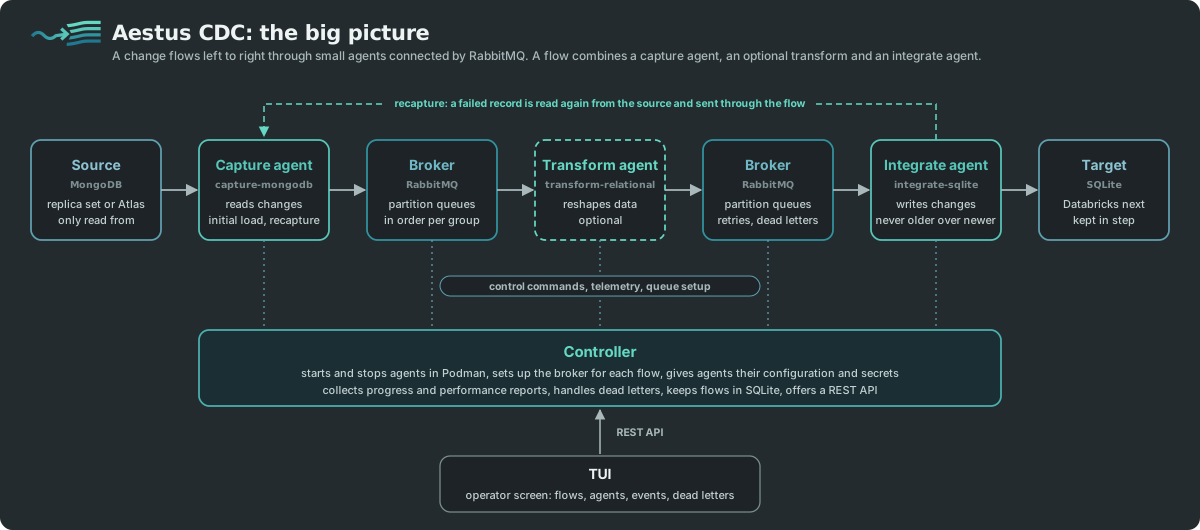
The capture agent follows the source's own change log or change feed. It copies existing records first, opening the stream before it starts so no change slips through, and labels every change with its key, group and source version.
RabbitMQ quorum queues hold every change until the next agent confirms it. Related records, such as an item and its stock, share a partition and stay in order; unrelated ones move in parallel.
Optionally reshape the data on the way, with a predefined transform (documents to tables, tables to documents or graphs, text to embeddings) or a fully custom one written in Go, Python or C#. Flows without a transform store the records as they are.
The integrate agent writes each change in a way that is safe to repeat, and never lets an older change overwrite a newer one. If a write fails, it asks for the record again and keeps going.
The same guarantees for every source and every target.
A new flow copies every existing record, then streams changes. The stream opens before the copy starts, so changes made during the load are never lost, and an interrupted load resumes where it stopped.
Map documents to parent and child tables, rows to documents or graph nodes, and text to embeddings. Tables and indexes are created and widened automatically when the mapping grows.
Group related collections by a key, such as an item and its stock records. Changes for the same group are applied in order, while different groups are processed in parallel.
Checkpoints only move once the broker has stored a change. Every target row remembers the version of its last change, so late or repeated messages are ignored, and deleted rows cannot come back.
A failed write triggers a recapture: the current record is read again from the source and sent through the flow. Failed transformations retry after growing delays. What still fails waits in a dead-letter queue for one decision: retry, recapture or discard.
Use a predefined transform, such as the relational mapping, with configuration only. Need something else, such as masking personal data? Write the transform yourself: natively in Go, or in Python or C# through the C bindings. Reading, writing, retries and statistics are handled for you.
Define flows, start, stop and pause agents, watch throughput, lag and events live, and handle dead letters from the terminal UI. Everything it does is also available through a documented REST API.
Run several replicas of a transform or integrate agent: partitions spread across them and move to the others when one stops. A busy collection can be read by several capture readers at once.
Send complete documents, or only the fields that changed. When a change cannot be applied on its own, for example inside an array, Aestus fetches the full record instead of guessing.
Every system gets its own small agent: one to capture its changes, one to write to it. Combine any source with any target, from databases to application APIs and event brokers.
| System | As a source | As a target |
|---|---|---|
| Relational Databases | ||
| PostgreSQL | Logical decoding of the WAL | Tables, JSONB, pgvector |
| MySQL and MariaDB | Binlog row events | Tables, JSON |
| SQL Server and Azure SQL | CDC or Change Tracking | Tables, vector columns |
| Oracle Database | LogMiner on the redo logs | Tables, vector columns |
| SQLite | Change-log triggers | Tables or documents |
| Databricks | Delta Change Data Feed | Delta tables, VARIANT |
| Snowflake | Change tracking | Tables, VARIANT |
| Document Databases | ||
| MongoDB and Atlas | Change streams | Documents, embedded children, deltas |
| Cosmos DB and DocumentDB | Change streams and change feed | Documents |
| Amazon DynamoDB | DynamoDB Streams | Items, embedded children |
| Google Firestore | Listeners and exports | Documents |
| Apache Cassandra | CDC commit log | Tables, ordered by write time |
| Graph Databases | ||
| Neo4j and AuraDB | Change data capture | Nodes and relationships |
| Amazon Neptune | Neptune Streams | Nodes and relationships |
| Graphs in PostgreSQL, MongoDB, SQL Server and Oracle | Through the host database | Vertex and edge tables, references |
| Vector & Search Databases | ||
| Elasticsearch and OpenSearch | Scan, for migrations | Search documents with vectors |
| Pinecone, Qdrant, Weaviate, Milvus | Scan, for migrations | Vectors with metadata |
| Vector columns in your database | Through the host database | pgvector, Atlas Vector Search, Oracle, SQL Server, Cassandra |
| Databricks Vector Search, Snowflake Cortex Search | Through the platform | Fresh source tables the platform indexes |
| APIs & Event Brokers | ||
| Apache Kafka, Confluent, MSK, Redpanda | Consumer groups with committed offsets | Keyed events, compacted topics |
| RabbitMQ | Queues and streams | Exchanges with routing keys |
| Azure Service Bus | Queues and topics, with sessions | Messages ordered by session |
| Azure Event Hubs | Partitions with checkpoints | Events by partition key |
| AWS SQS, SNS, Kinesis, EventBridge | FIFO queues and shards | Message groups and events |
| Google Pub/Sub | Subscriptions with ordering keys | Messages with ordering keys |
| NATS and MQTT | JetStream and topic subscriptions | Subjects and topics |
| REST APIs and webhooks | Polling, or webhooks received | Calls with idempotency keys |
| gRPC services | Server streams | Calls to your methods |
Operational, reporting and analytical SQL databases, from PostgreSQL to the lakehouse.
ExploreDocument, key-value and wide-column stores: MongoDB and its relatives, DynamoDB, Firestore and Cassandra.
ExploreProperty graphs in Neo4j and Neptune, and graphs kept inside PostgreSQL, MongoDB, SQL Server and Oracle.
ExploreSearch engines and vector stores that serve search, recommendations and AI assistants.
ExploreApplication APIs and the enterprise message brokers: deliver changes into systems and onto event streams, or start a flow from them.
ExploreThe broker, the controller and every agent run as containers inside your own network. Changes go straight from your source to your target.
One small image per agent. A few scripts start the broker, the controller and a development database; the controller starts and supervises the agents. Kubernetes, Docker and systemd are next.
Passwords and connection strings live in Podman secrets and reach agents as environment variables. Configuration files never contain them.
Aestus is an enterprise product, delivered together with consulting: we work with your team to design flows and mappings, run them in your network, and keep them healthy.
Relational databases, the lakehouse, document and NoSQL stores, graph databases, search engines, vector stores, application APIs (REST, webhooks, gRPC) and event brokers (Kafka, RabbitMQ, Azure Service Bus, Event Hubs and more): see Sources & Targets. Every flow gets an initial load, ordered delivery per group, recapture of failed records and dead-letter handling.
You group related collections by a key, such as an item and its stock records by item id. All changes for one group key travel through the same partition queue and are applied in order; other groups move in parallel.
The integrate agent does not stop. It asks the capture agent to read the record again from the source and sends the current version through the flow. If that keeps failing, the record waits in a dead-letter queue until an operator chooses to retry, recapture or discard it.
Yes. Transforms are predefined or fully custom. Predefined transforms, such as the relational mapping, need configuration only. A custom transform is one function you write, natively in Go or in Python or C# through the C bindings; the transform template wraps it with everything an agent needs.
No. The broker, controller and agents run in your network, and changes travel only between your source, the broker and your target.
Aestus is an enterprise product, delivered with consulting from Helium Consulting Services and Providentia World Wide. Early access is closed at this moment; write to info@aestus-cdc.com to talk about your use case.
Aestus is Latin for the tide: the swell of the sea that rises and falls on its own rhythm and never stops. The Romans also used it for heat and for surging motion, the restless movement of water pulled by forces far away.
That is what this software does with data. A change made in one database does not sit still: it is lifted by the capture agent, carried by the current through the broker, and set down on another shore, in the target, exactly where it belongs. Like the tide, Aestus is patient and relentless. It keeps moving while systems sleep, it returns to pick up anything it left behind (a recapture is just the tide coming back in), and it never lets the water flow backwards: an older wave never washes away a newer one.
You do not command the tide; you set it up and let it run. Configure a flow, start it, and the data keeps arriving, change after change, the way the sea keeps arriving at the coast.